> ## Documentation Index
> Fetch the complete documentation index at: https://docs.orq.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# LLM traces for debugging
> Explore step-by-step details of every LLM generation. Debug RAG pipelines, evaluators, guardrails, and caching with full workflow visibility and cost tracking.
## What are Traces
With **Traces**, dive into the workflow of each model generation and understand the inner workings of an LLM call on **Orq.ai**.
Traces correspond to events within the generations. Events within a [Deployment](/ai-studio/ai-engineering/deployments) can be various:
* [Evaluators](/ai-studio/optimize/evaluators) & [Guardrails](/ai-studio/ai-engineering/deployments#evaluators-and-guardrails)
* Retrieval using [Knowledge Base](/ai-studio/ai-engineering/knowledge-bases)
* [Embeddings](/ai-studio/ai-engineering/knowledge-bases#embedding-models)
* [Chunking](/ai-studio/ai-engineering/knowledge-bases#datasource-and-chunking)
* [Caching](/ai-studio/ai-engineering/deployments#cache)
* [Retries and Fallbacks](/ai-studio/ai-engineering/deployments#primary-model-retries-and-fallback)
## Creating Traces
Traces are automatically generated when using Orq.ai Deployments. Create custom traces for application code using framework instrumentation or the Orq.ai SDK.
### Framework Instrumentation
For popular AI frameworks and libraries, use automatic instrumentation with OpenTelemetry:
Explore automatic instrumentation for OpenAI, LangChain, LlamaIndex, CrewAI, Autogen, and 15+ other frameworks with OpenTelemetry integration.
### Custom Tracing using the @traced decorator
For custom functions or application workflows, use the `@traced` decorator from the [Python SDK](https://github.com/orq-ai/orq-python). It works with both synchronous and async functions:
```python Sync theme={"theme":{"light":"github-light","dark":"github-dark"}}
import os
from orq_ai_sdk import Orq
from orq_ai_sdk.traced import traced
@traced(name="process_document", type="agent")
def process_document(doc_id: str):
result = {"status": "processed", "doc_id": doc_id}
return result
@traced(name="fetch_context", type="retrieval")
def fetch_relevant_context(query: str):
return {"context": "relevant information", "sources": ["doc1", "doc2"]}
@traced(name="format_response", type="function")
def format_response(raw_output: str, metadata: dict):
return {"formatted": raw_output.strip(), "metadata": metadata}
@traced(name="document_pipeline", type="agent")
def document_pipeline(orq, doc_id: str):
doc = process_document(doc_id)
context = fetch_relevant_context("user query")
response = orq.responses.create(
model="agent/simple-agent",
input=f"Summarize this document: {doc['status']}. Context: {context['context']}",
)
return format_response(response.output[0]["content"][0]["text"], {"doc_id": doc_id})
with Orq(api_key=os.getenv("ORQ_API_KEY")) as orq:
result = document_pipeline(orq, "doc-123")
print(result)
```
```python Async theme={"theme":{"light":"github-light","dark":"github-dark"}}
import os
import asyncio
from orq_ai_sdk import Orq
from orq_ai_sdk.traced import traced
@traced(name="process_document", type="agent")
async def process_document(doc_id: str):
result = {"status": "processed", "doc_id": doc_id}
return result
@traced(name="fetch_context", type="retrieval")
async def fetch_relevant_context(query: str):
return {"context": "relevant information", "sources": ["doc1", "doc2"]}
@traced(name="format_response", type="function")
async def format_response(raw_output: str, metadata: dict):
return {"formatted": raw_output.strip(), "metadata": metadata}
@traced(name="document_pipeline", type="agent")
async def document_pipeline(orq, doc_id: str):
doc = await process_document(doc_id)
context = await fetch_relevant_context("user query")
response = await orq.responses.create_async(
model="agent/simple-agent",
input=f"Summarize this document: {doc['status']}. Context: {context['context']}",
)
return await format_response(response.output[0]["content"][0]["text"], {"doc_id": doc_id})
async def main():
async with Orq(api_key=os.getenv("ORQ_API_KEY")) as orq:
result = await document_pipeline(orq, "doc-123")
print(result)
asyncio.run(main())
```
The result is a single trace with each decorated function appearing as a nested span:
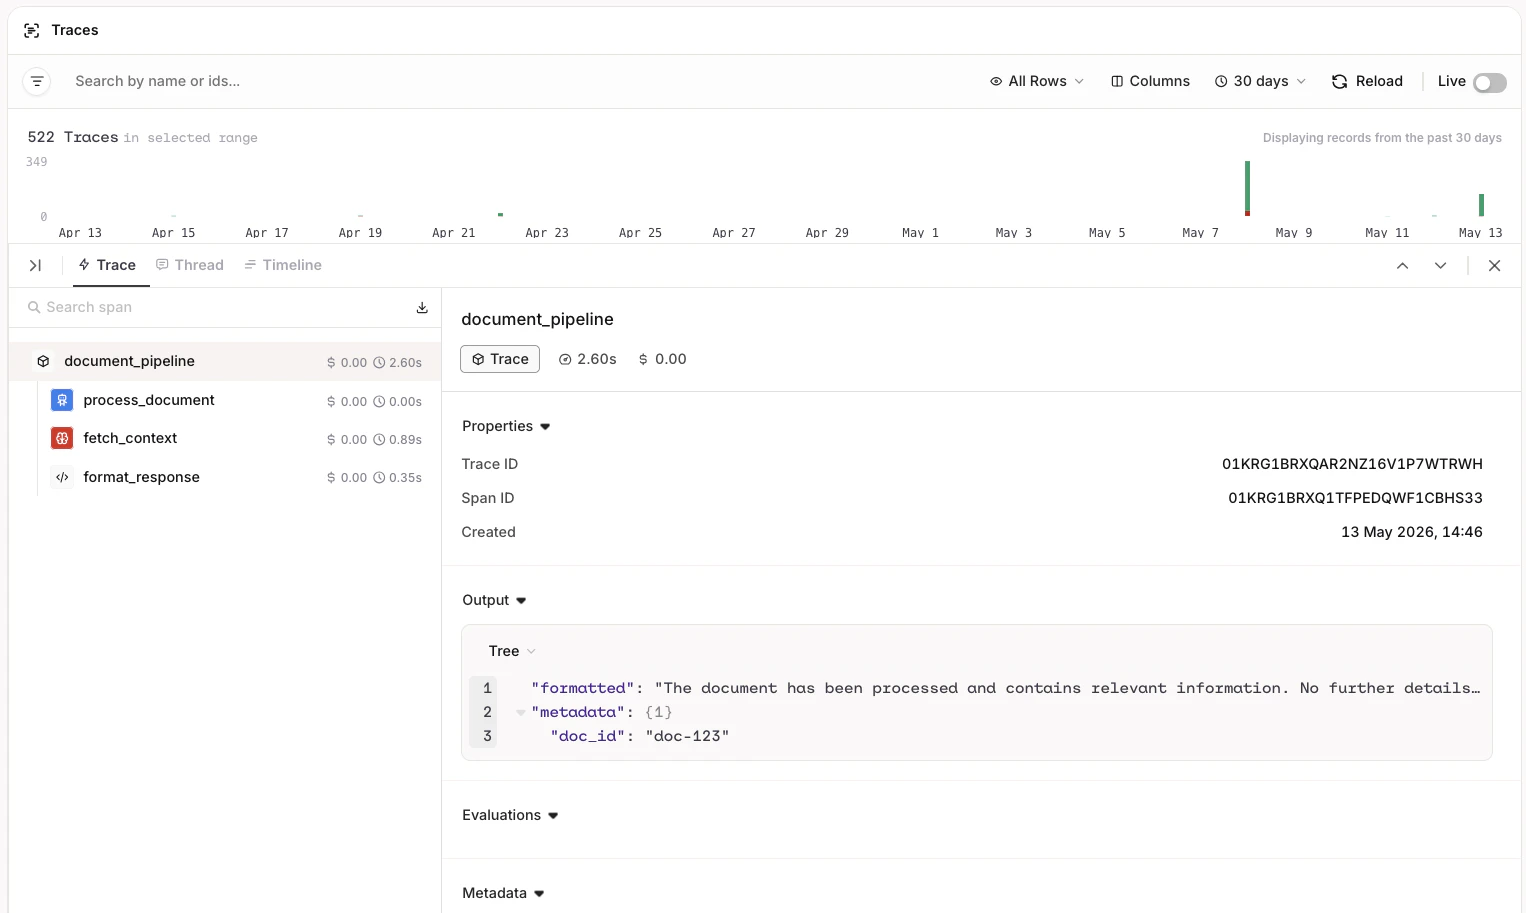 The `@traced` decorator supports the following span types:
| Type | Description |
| ----------- | ------------------------------------------------- |
| `agent` | A high-level orchestration step or agent workflow |
| `embedding` | An embedding generation operation |
| `function` | A general-purpose function or processing step |
| `llm` | A direct LLM API call |
| `retrieval` | A retrieval or knowledge lookup operation |
| `tool` | An external tool call |
Capture or suppress inputs/outputs with `capture_input` and `capture_output`, and attach custom metadata with the `attributes` parameter:
```python theme={"theme":{"light":"github-light","dark":"github-dark"}}
@traced(
name="process_document",
type="agent",
capture_input=False,
capture_output=False,
attributes={"version": "1.0", "env": "production"}
)
def process_document(doc_id: str):
...
```
## How to Lookup Traces
To find traces, head to the **AI Studio** and to the **Traces** section.
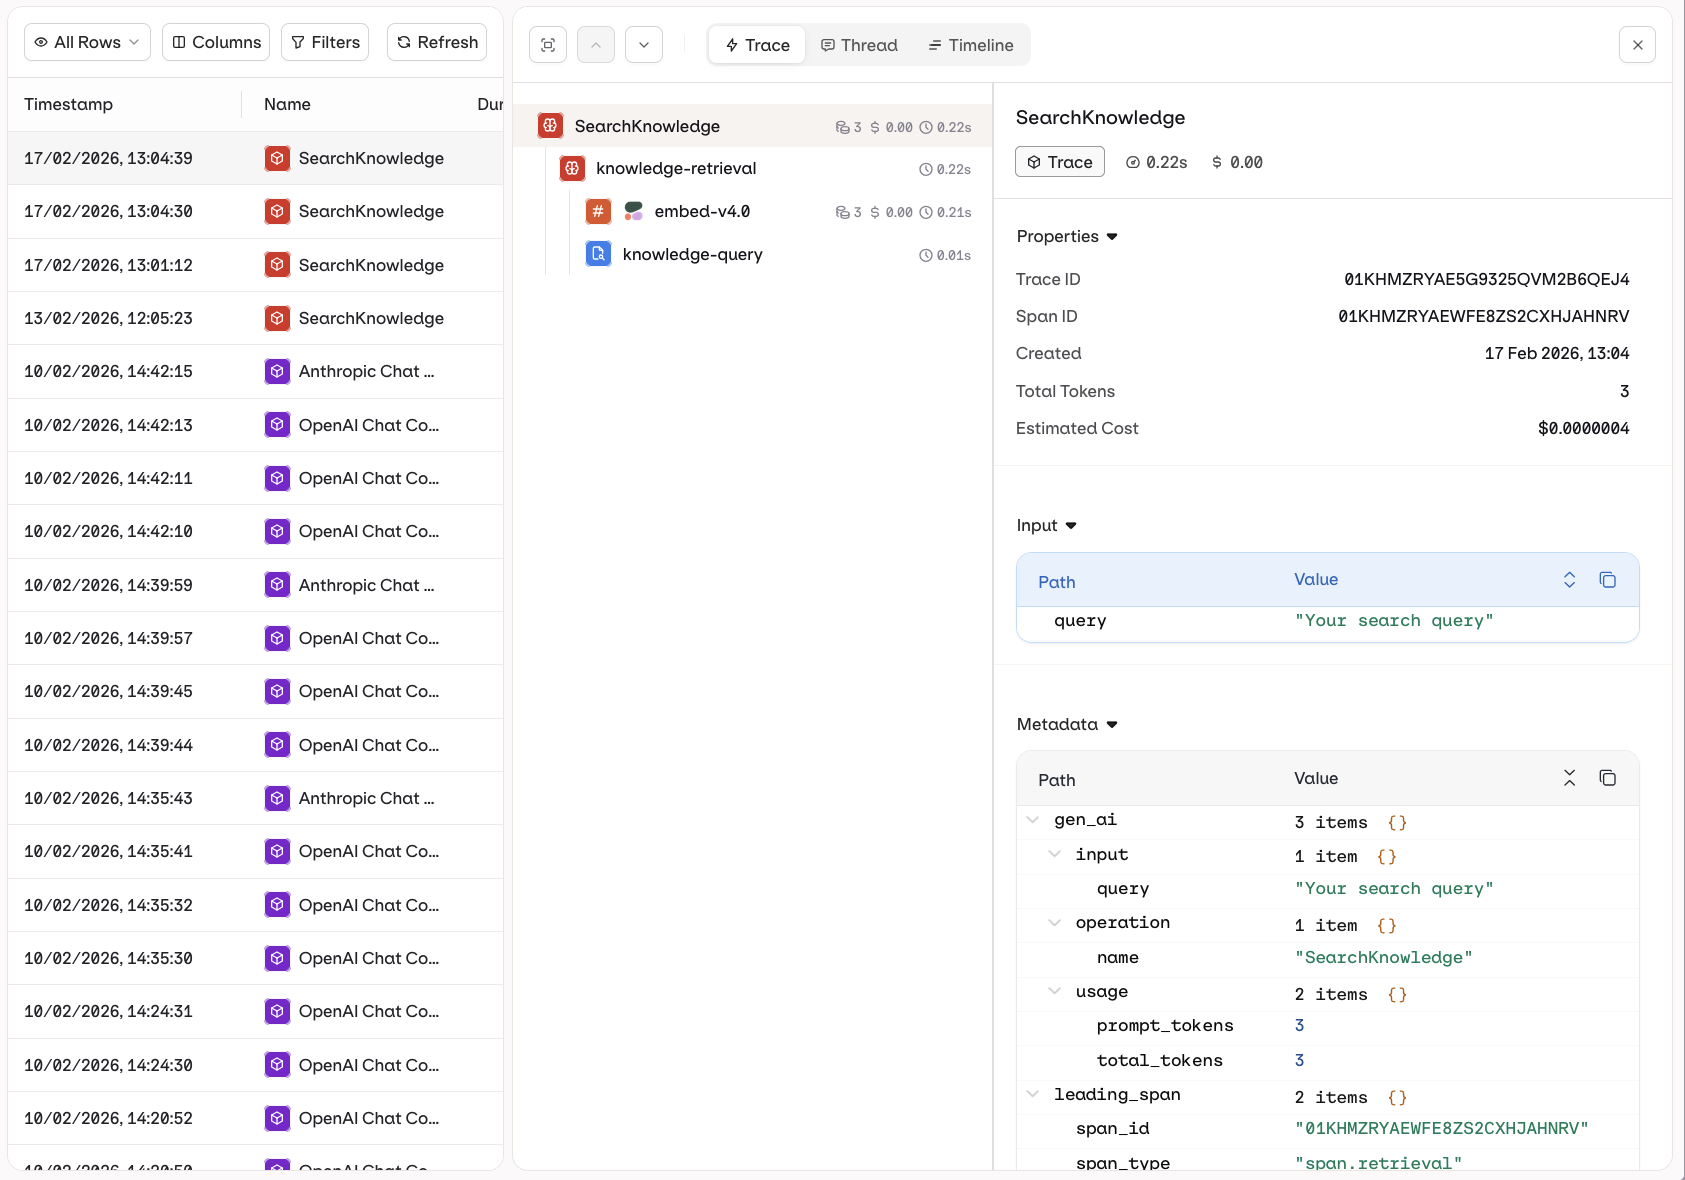 Explore traces for each action taken during a generation:
* The left column shows the list of Traces available.
* By selecting a trace, the middle column opens, showing the **hierarchy** of events shown in order of execution.
* By selecting a single trace, the right column opens, showing details for the specific step.
### Trace Views
Each trace can be inspected in three views to suit different debugging and analysis needs.
The **Trace** view shows the full execution tree for a single run. Each step is displayed hierarchically, including LLM calls, tool invocations, knowledge retrievals, and memory interactions. Use this view to inspect inputs, outputs, token usage, and latency at every step.
For multi-agent runs, the hierarchy renders as an **agent graph**: parent agents and their sub-agent calls are shown as a nested tree, making it easy to follow how work was delegated across agents and where time was spent. See [Agent Graphs](/ai-studio/observability/agent-graphs) for how graphs are produced and how to debug delegation paths.
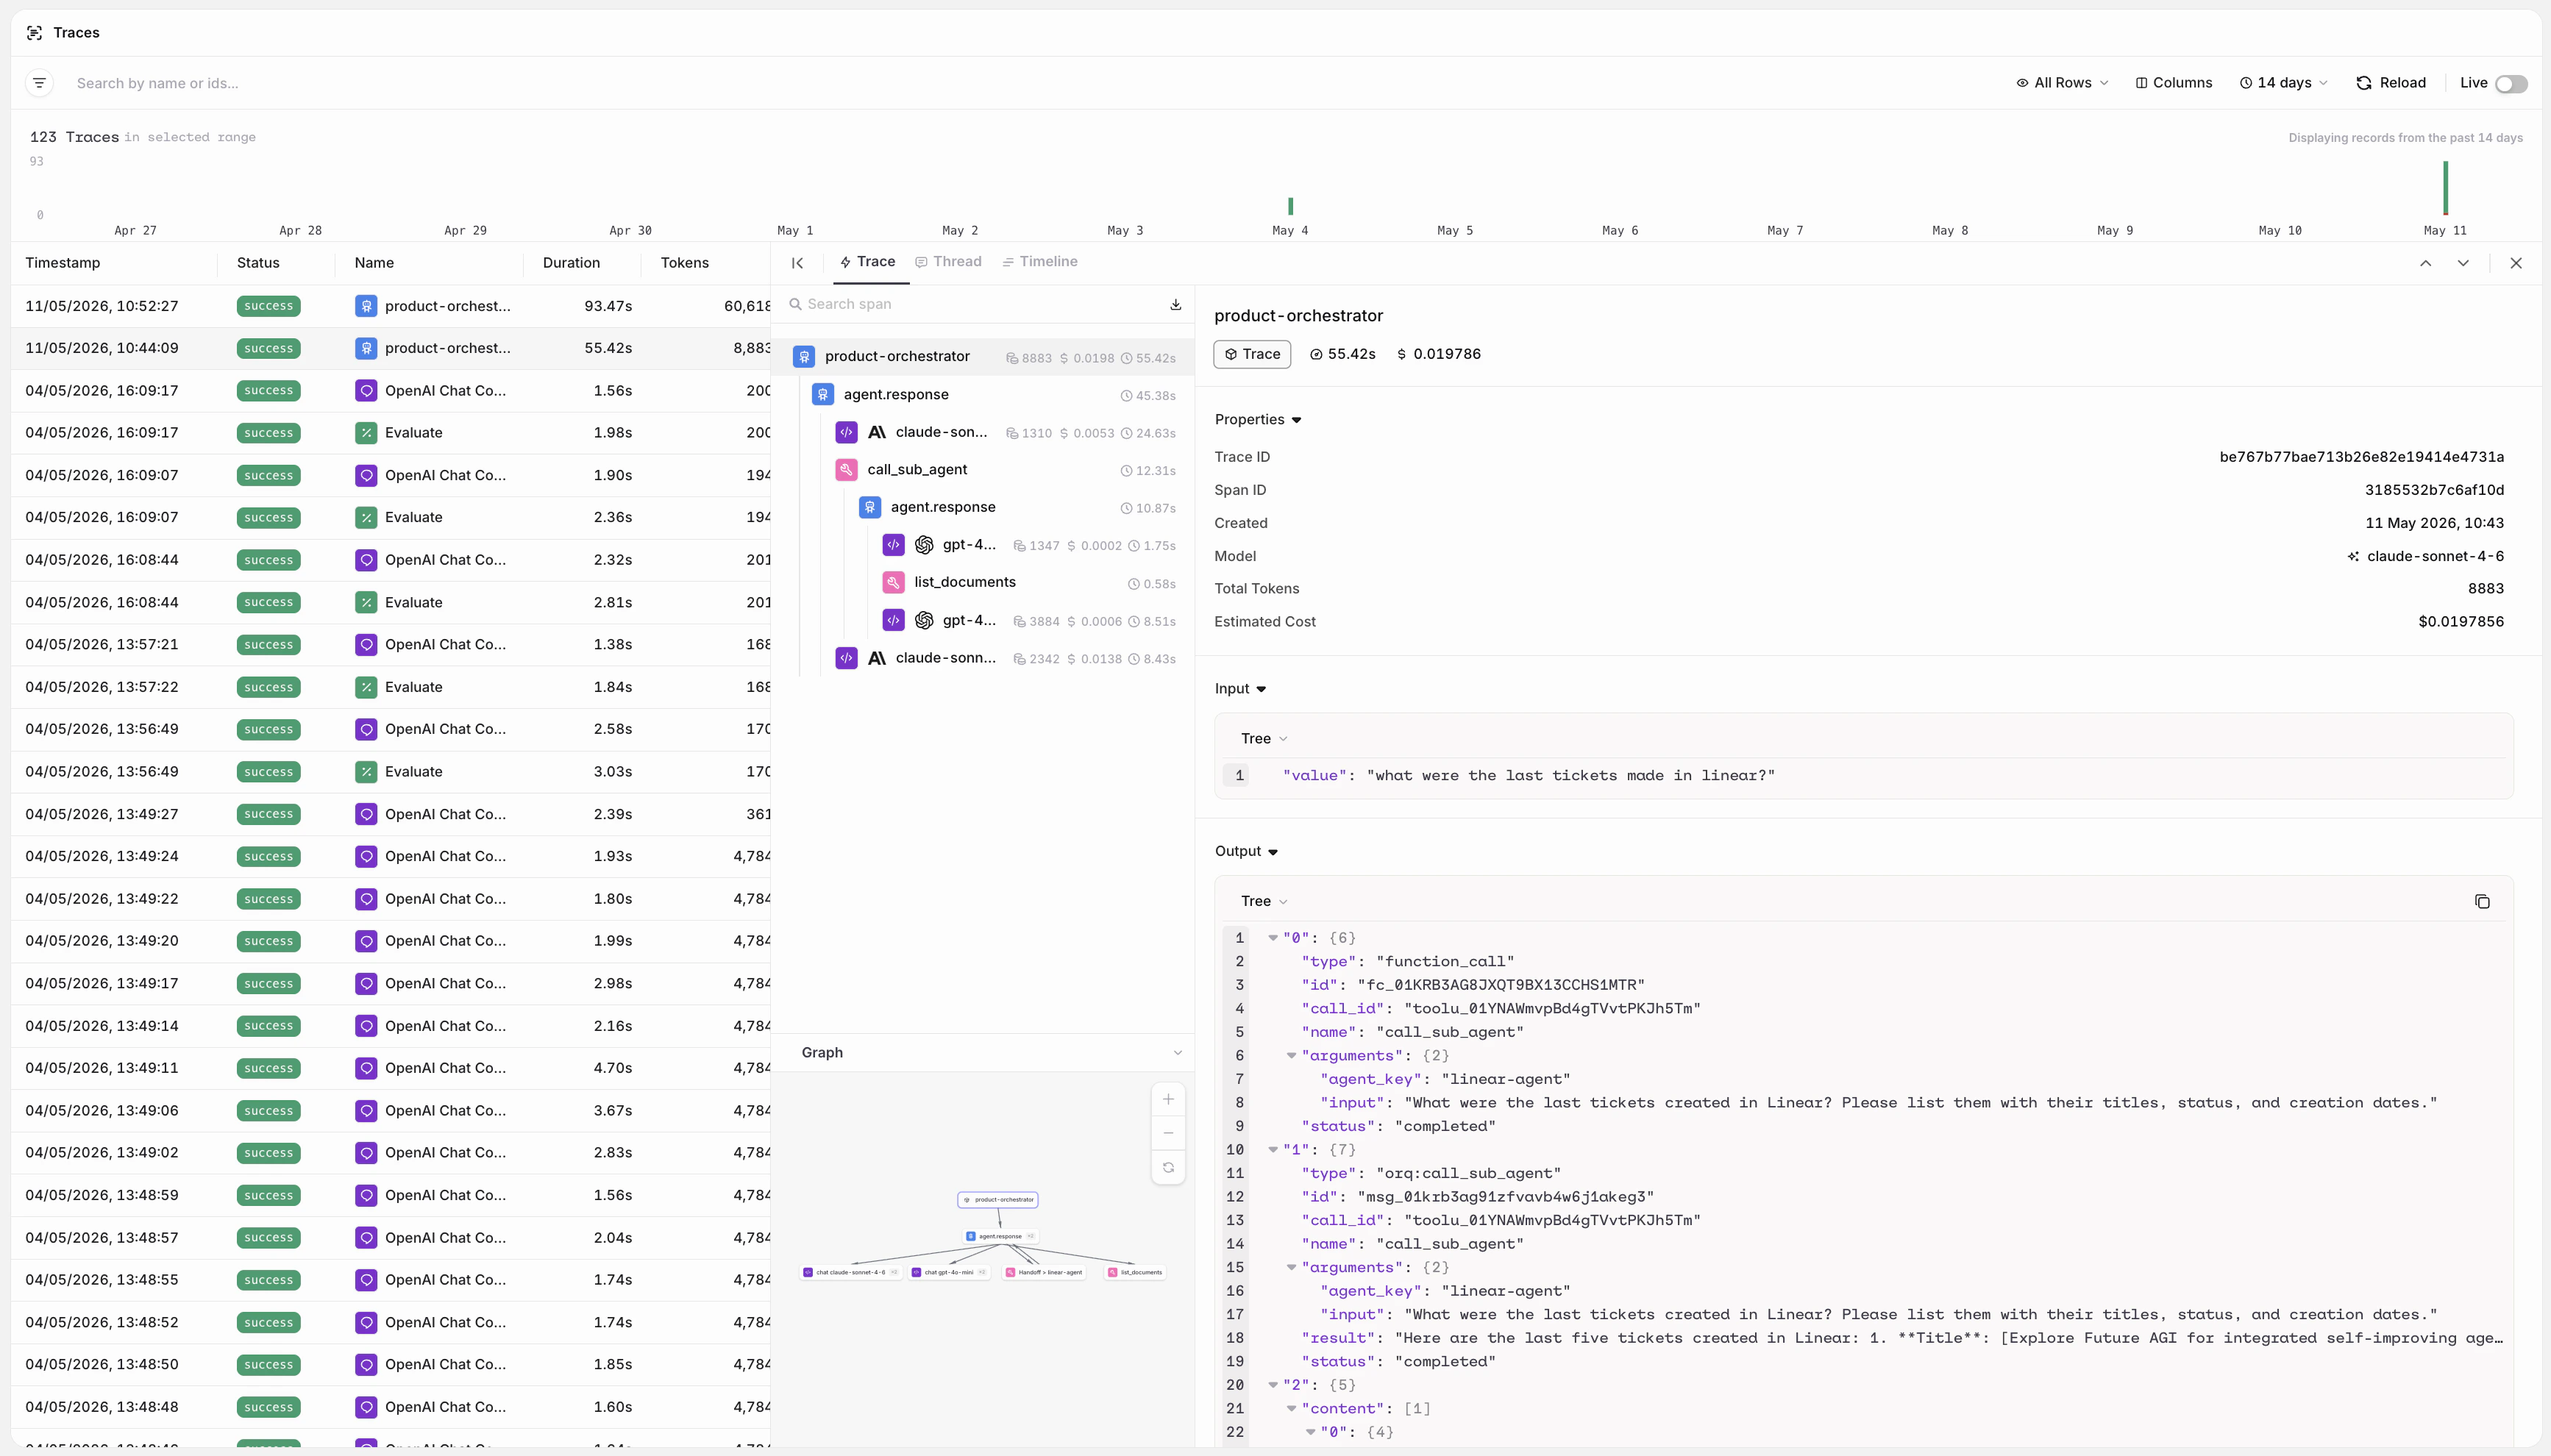 Erroring Traces are shown with a icon.
Manually evaluate responses using **Annotations** directly on individual spans. Annotations defined in the project are available on all spans automatically. Learn more in [Annotations](/ai-studio/observability/annotations).
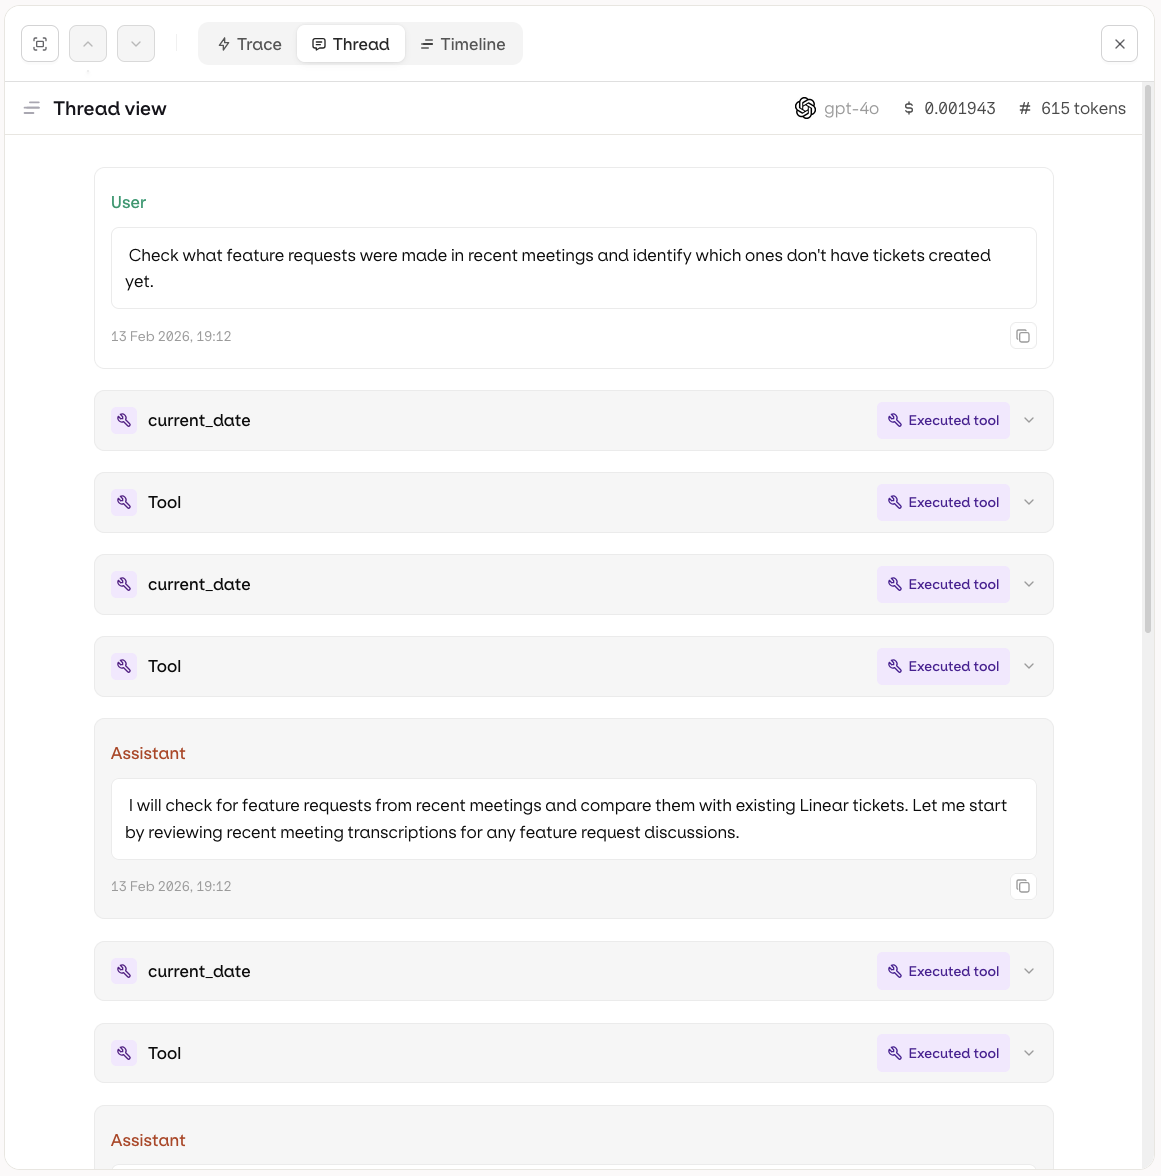
The **Thread** view presents the execution as a conversation thread, showing the sequence of messages exchanged between the user, the agent, and any tools. Use this view to follow the narrative flow of a task and understand how the agent reasoned through a problem.
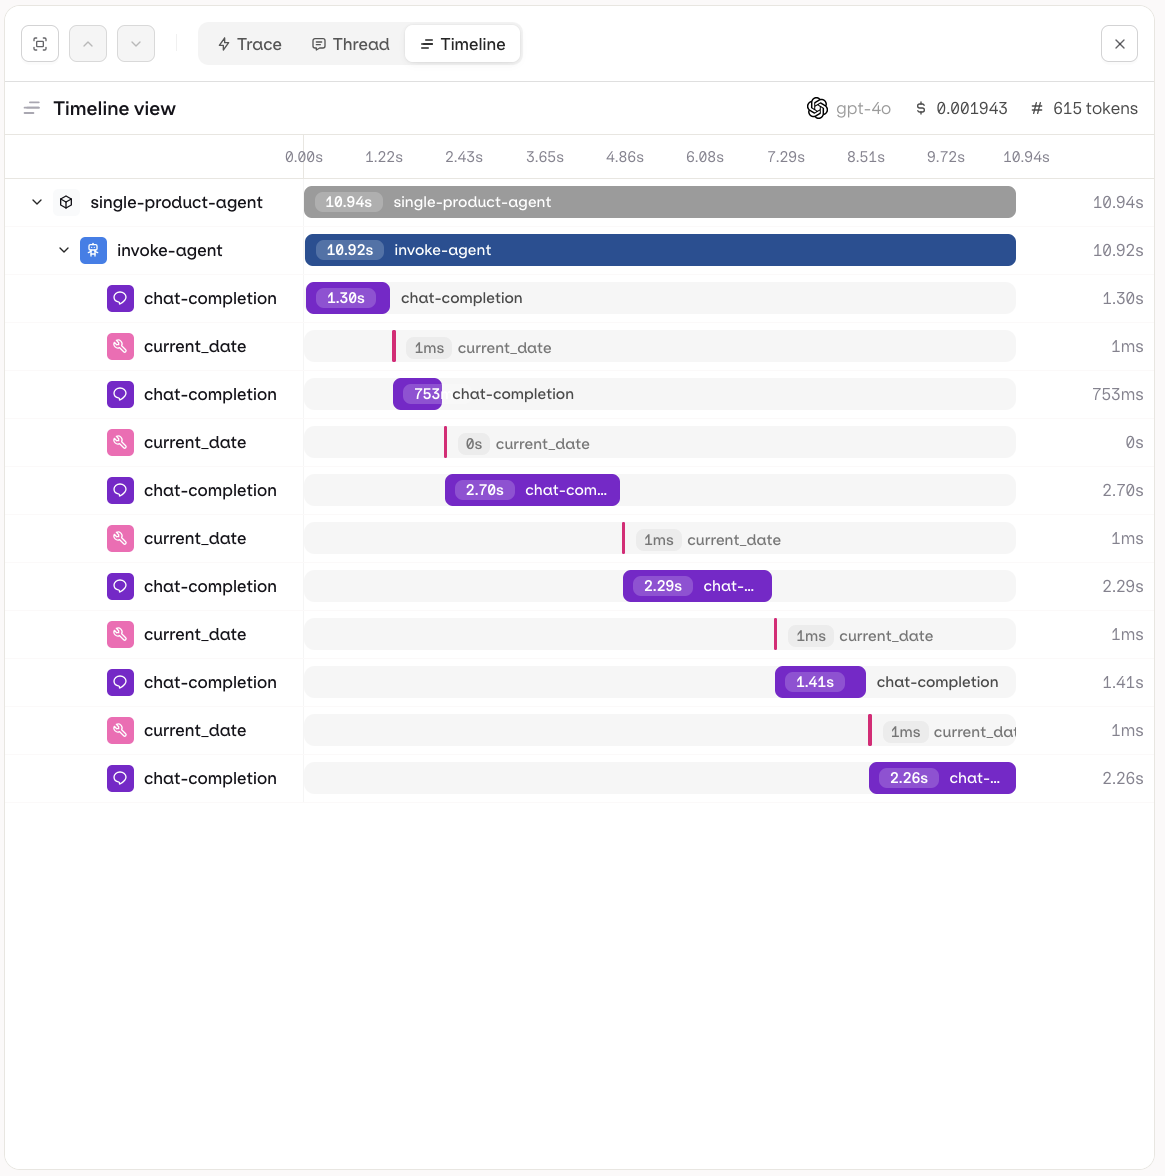
 The **Timeline** view shows execution steps plotted against time, making it easy to identify bottlenecks, measure step durations, and understand which operations ran sequentially or in parallel.
 ### Viewing Errors
Traces that encountered an error are marked with a red **error** status badge in the list. Use the **Status** filter to scope the list to errors only and identify failing traces quickly.
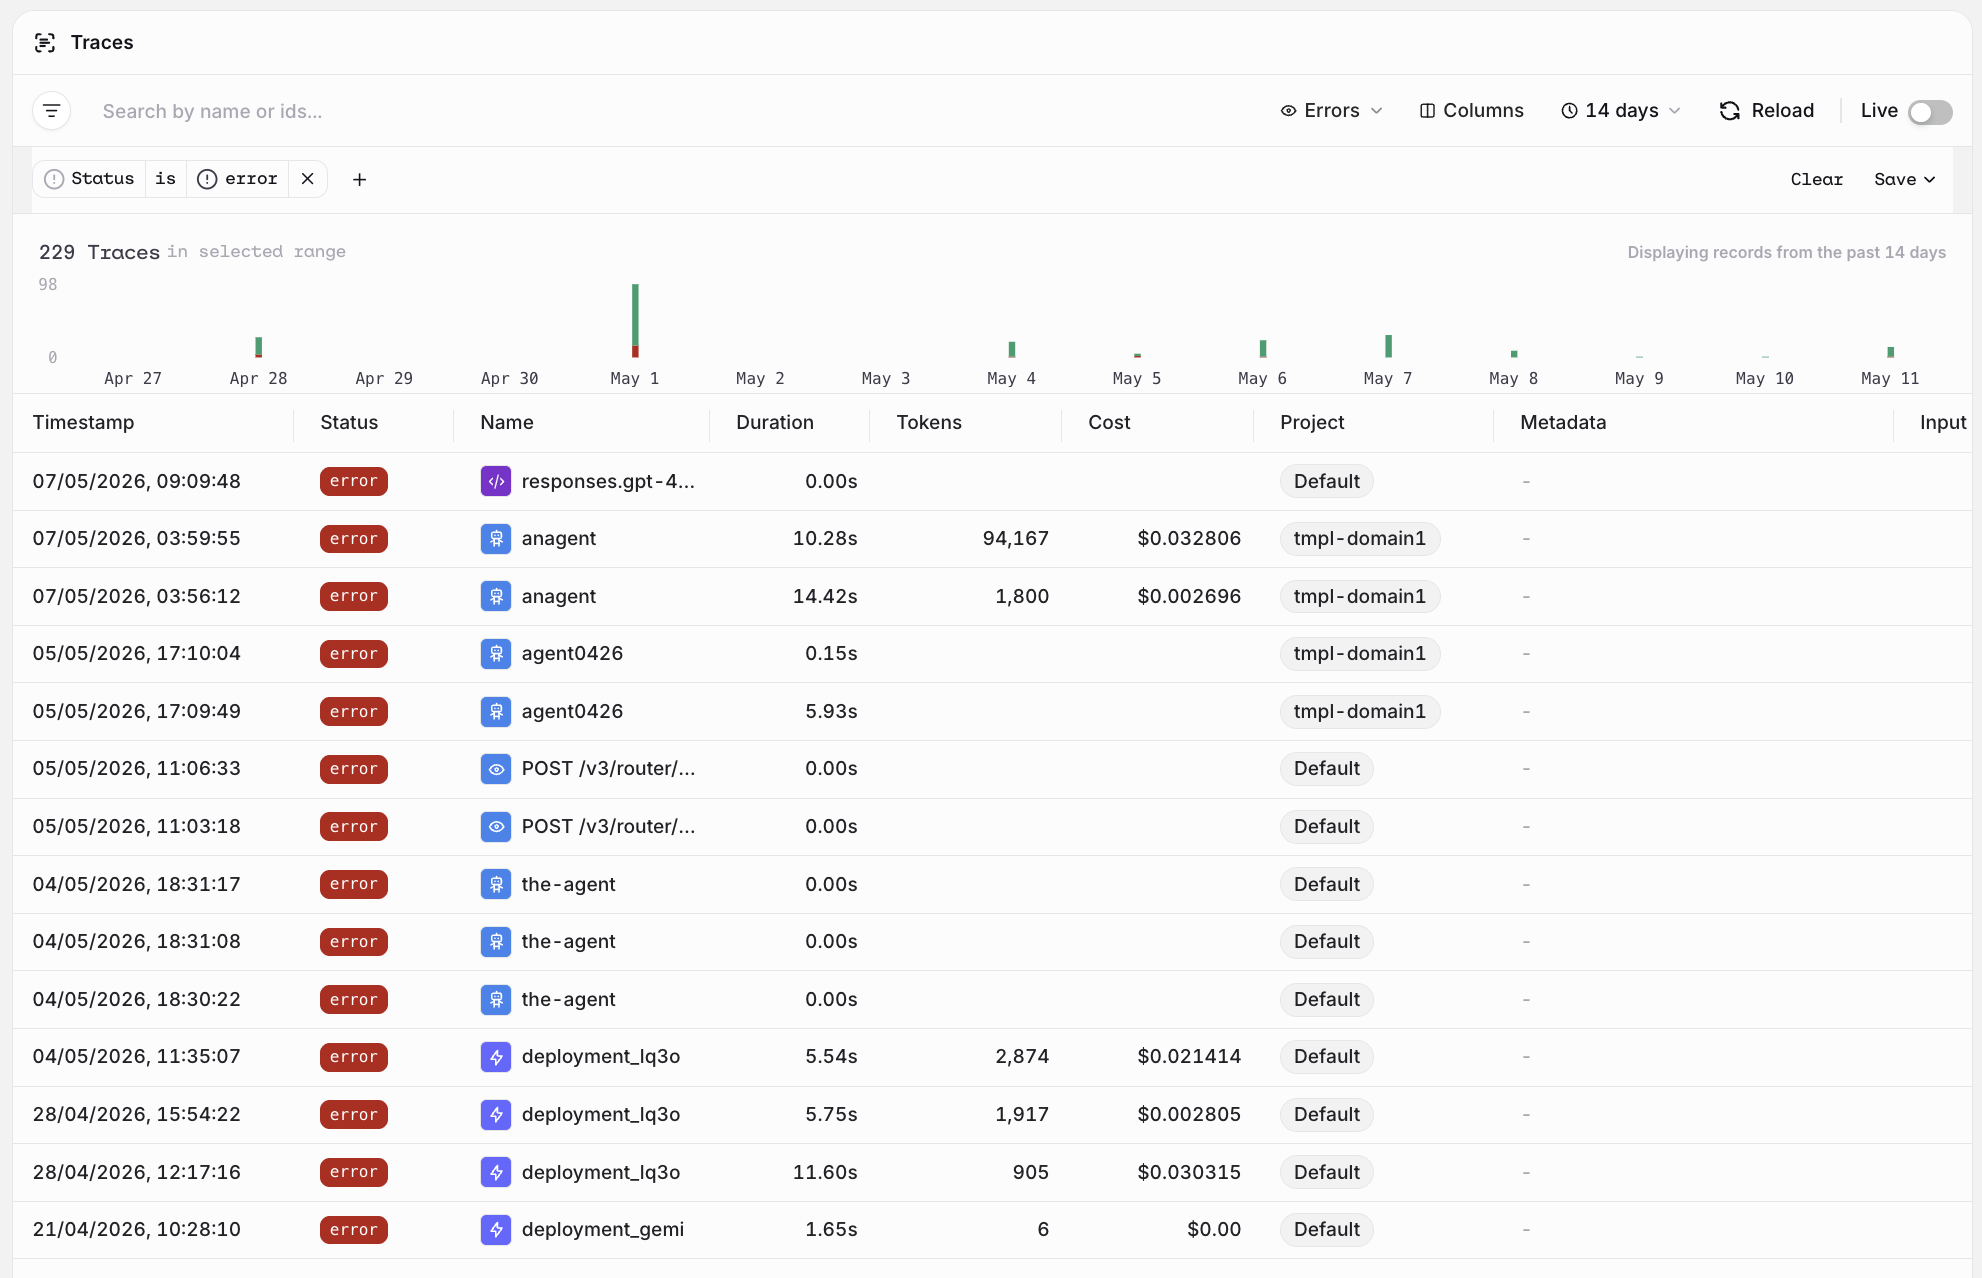 The **Status** filter combines with any other filter, for example:
* Filter by **Status: error** and an **Identity** to see all errors for a specific user.
* Combine with **Project** or **Metadata** to narrow down failures to a particular environment or deployment.
### Filtering Traces
Click next to the search bar to open the filter menu. Select a category to expand a searchable list of values and check one or more to apply.
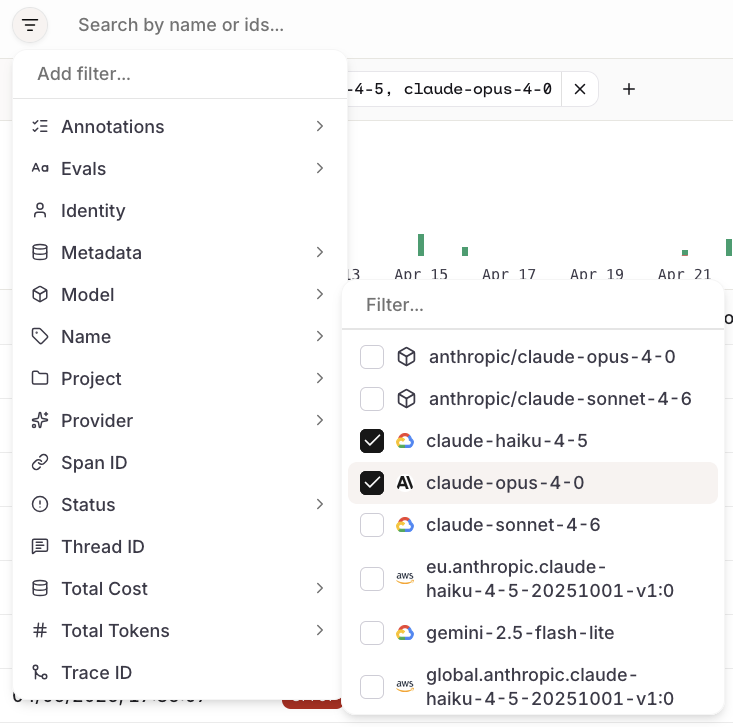 When working with [Agents](/ai-studio/ai-engineering/run-agents#traces), access traces directly from the Agent page with automatic filtering for that specific agent.
The following filter categories are available:
| Filter | Description |
| ---------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Annotations** | Filter by annotation labels applied to traces. |
| **Evals** | Filter by evaluator results attached to traces. |
| **Identity** | Filter by the identity that triggered the trace. |
| **Messages** | Filter by the number of iterations in the agent's execution loop, not the number of user or assistant messages. A value of 1 means the model answered directly; each sequential tool round adds one. Parallel tool calls within a single round do not increase the count. |
| **Metadata** | Filter by metadata fields attached to traces. |
| **Model** | Filter by the model used in the trace. |
| **Name** | Filter by trace name. |
| **Project** | Filter by the project the trace belongs to. |
| **Provider** | Filter by the model provider. |
| **Span ID** | Filter by a specific span identifier. |
| **Status** | Filter by the status of the trace (e.g. error, success). |
| **Thread ID** | Filter by the thread the trace belongs to. |
| **Total Cost** | Filter by the total cost of the trace. |
| **Total Tokens** | Filter by the total token count of the trace. |
| **Trace ID** | Filter by a specific trace identifier. |
The Messages count is calculated only for Agents running on **Orq.ai**. Traces imported from external frameworks have no value unless the instrumentation sends a numeric `agent.iterations.count` attribute.
Multiple filters can be combined. To remove a filter, click next to it in the filter bar.
### Configuring Column
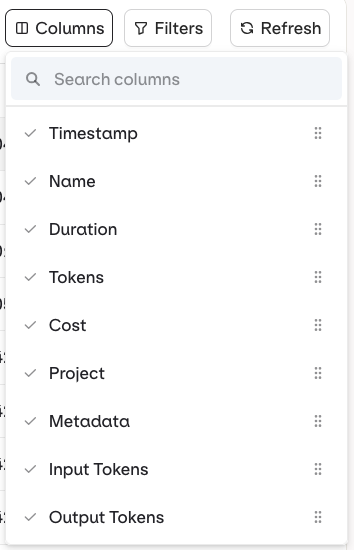
Columns can be enabled and toggled to display more available data in the traces list.
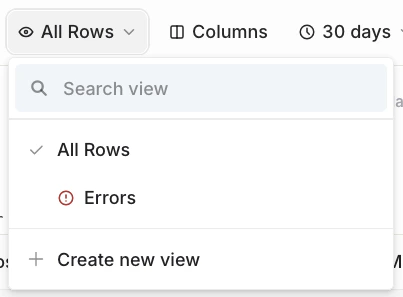
 ### Creating Custom Views
Save frequently used filter combinations as reusable views:
1. Set the desired filters
2. Click All Rows (top right)
3. Select Create New View
4. Enter a title for the view
5. Optionally check **Set view private** (default is shared with project members)
6. The filtered view is saved and accessible from the All Rows dropdown
A custom view filtering for all **Errors** is available by default.
 ## Review Traces
Click Review in the toolbar to open the review screen and step through traces one by one. Applying one or more [filters](#filtering-traces) first narrows the review queue to matching traces; with no filter active, Review steps through the current list.
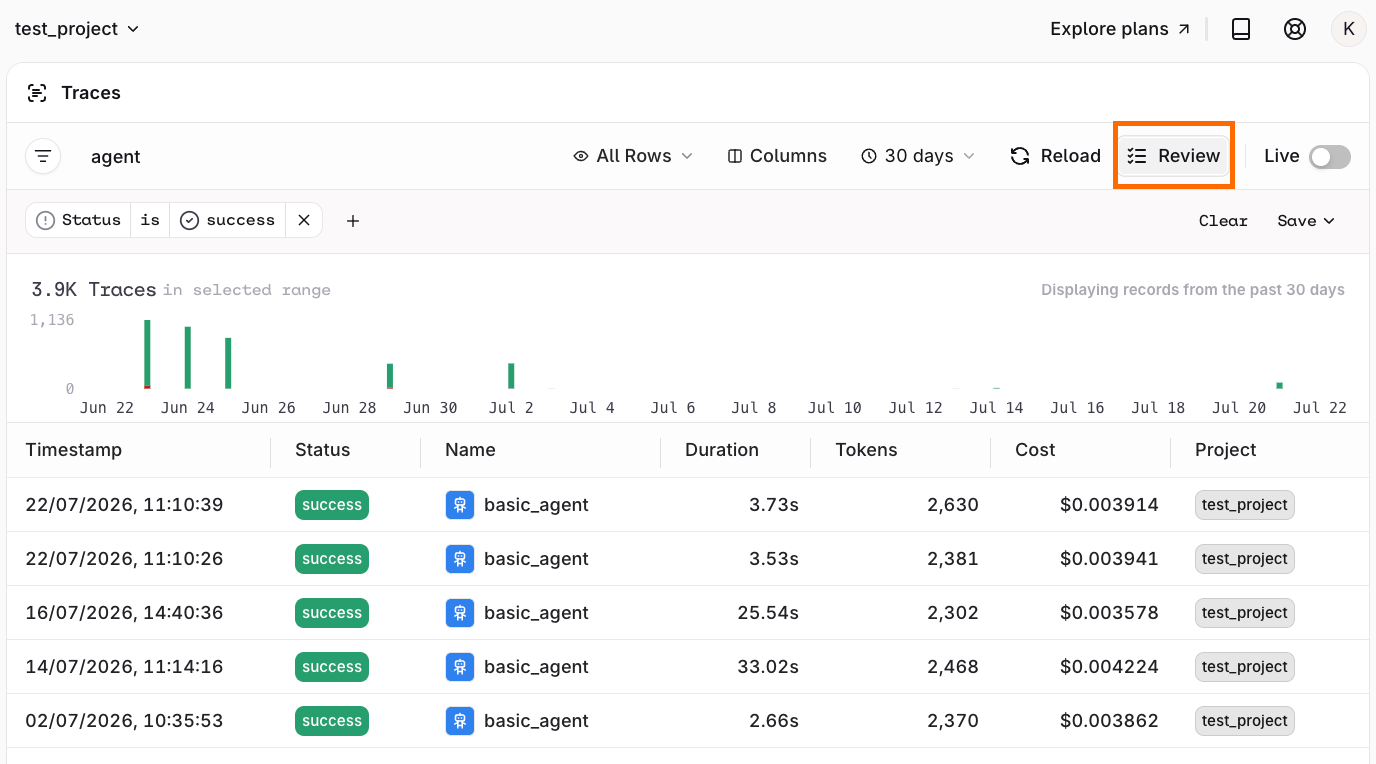 The screen follows the same three-panel layout as [Annotation Queues](/ai-studio/observability/annotation-queues#use-annotation-queues):
* **Left**: Inputs and Metrics for the selected span.
* **Center**: Full trace conversation.
* **Right**: [Annotation](/ai-studio/observability/annotations) controls for manual review. Select in the Annotations panel header to [create a new annotation](/ai-studio/observability/annotations#create-annotations) without leaving the screen.
Annotations applied here are written back to the span and are queryable via the [**Orq MCP**](/ai-studio/integrations/code-assistants/orq-mcp).
## Correct an Evaluator Result
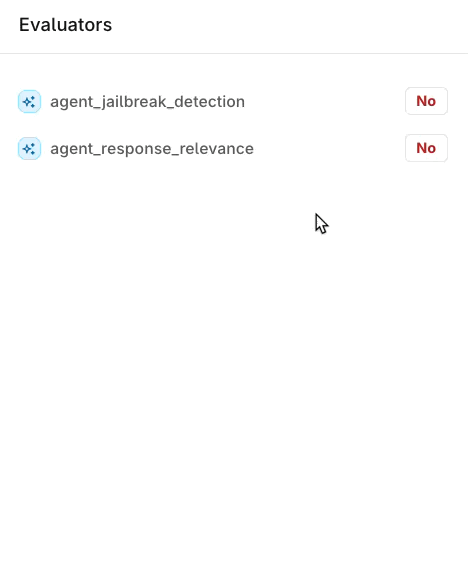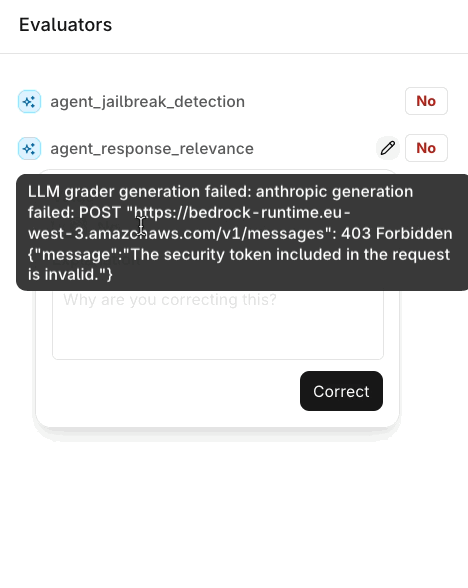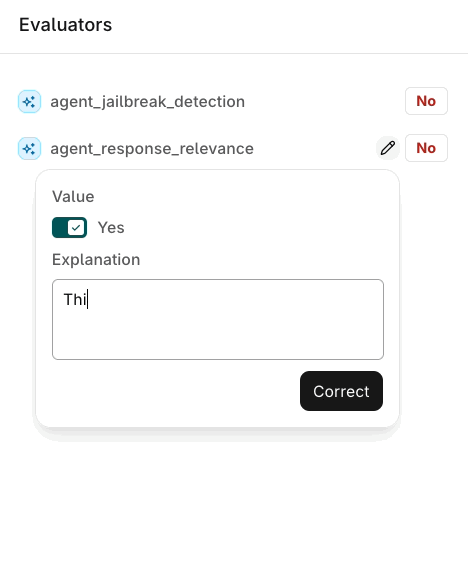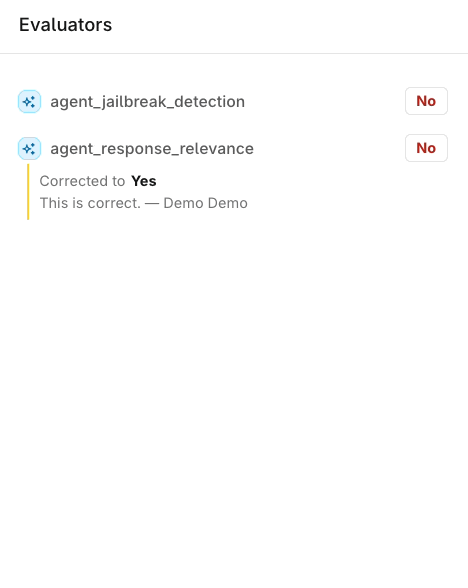
Hover an Evaluator result to reveal a , and select it to open a popover with:
* **Value**: the corrected result, matching the Evaluator's own output type (a toggle for boolean Evaluators, a text or number field otherwise).
* **Explanation**: an optional comment.
Select **Correct** to submit, or **Update** to replace an existing correction. The correction appears under the original result as **Corrected to \**, along with the explanation and the reviewer's name.
 Corrections are written back to the Trace like any other annotation. This gives a basis to compare an Evaluator's own results against reviewer corrections over time, using that signal (for example through the [**Orq MCP**](/ai-studio/integrations/code-assistants/orq-mcp)) to see where an Evaluator's configuration may need adjustment.
This corrects the Evaluator's *result*, not the AI response text. For rewriting the response itself, use the Logs [**Add a Text Correction**](/ai-studio/observability/annotations#use-annotations) flow.
See [Correct an Evaluator Result](/ai-studio/observability/annotations#use-annotations) in the API & SDK tab for the API/SDK equivalent.
## Threads
Visualize conversation history as Threads to follow the full sequence of messages across an agent session.
## Reference
How token usage is captured and cost is calculated per LLM request.
Complete reference for all `orq.*` span attributes emitted on traces, webhook payloads, and trace exports.