> ## Documentation Index
> Fetch the complete documentation index at: https://docs.orq.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Release 4.15
> Release 4.15 brings Guardrail and Routing rules to Deployments, OAuth and egress controls to the MCP Gateway, and a Python editor for Evaluators.
Govern a **Deployment** the way an **Agent** is already governed, without touching the prompt. A **Deployment** invoke now runs through the same gateway pipeline as an **Agent**, so the Guardrail rules, Routing rules, and workspace plugins configured once for the workspace apply to **Deployments** too.
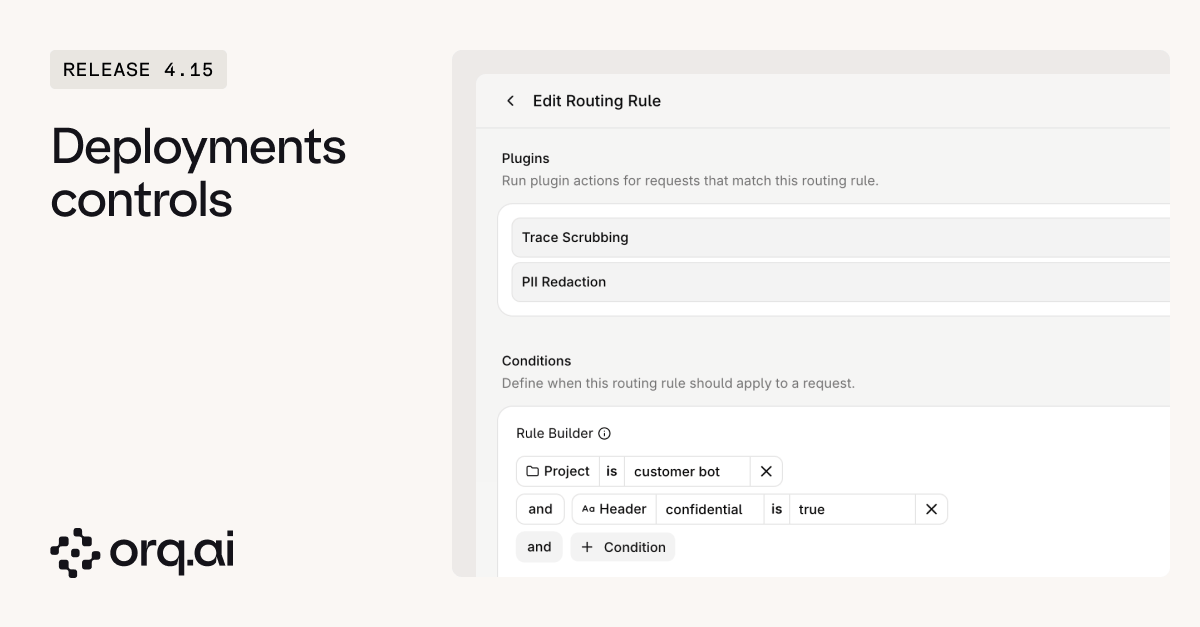 * **[Guardrail rules](https://docs.orq.ai/docs/ai-gateway/configuration/guardrail-rules) apply**: Block a **Deployment** request on PII, secrets, or a custom guardrail. A blocked invoke returns an error that names the failing guardrail instead of a `200`.
* **[Routing rules](https://docs.orq.ai/docs/ai-gateway/configuration/routing-rules) apply**: Match on header, identity, metadata, or project to swap the model, load balance, enable caching, and attach Trace scrubbing or PII redaction to exactly that traffic.
* **Workspace plugins are enforced**: The workspace [PII redaction](https://docs.orq.ai/docs/ai-gateway/features/plugins/pii-redaction) floor and other workspace-wide plugins run on every invoke, and a request can only add stricter rules on top.
* **Model access, budgets, and rate limits follow the Deployment**: Per-project model access, budgets, and rate limits are checked once the variant resolves, and the matched rules and budgets are recorded on the **Trace**.
Start with the [Guardrail rules](https://docs.orq.ai/docs/ai-gateway/configuration/guardrail-rules) and [Routing rules](https://docs.orq.ai/docs/ai-gateway/configuration/routing-rules) guides.
Connect Claude Code, Cursor, or any standards-compliant MCP client to an **MCP Gateway** with a browser sign-in instead of a pasted API key, and decide which hosts the gateway may reach and how long a tool call may run. The **MCP Gateway** now carries the access, network, and runtime controls that used to require a long-lived key and a trusting upstream.
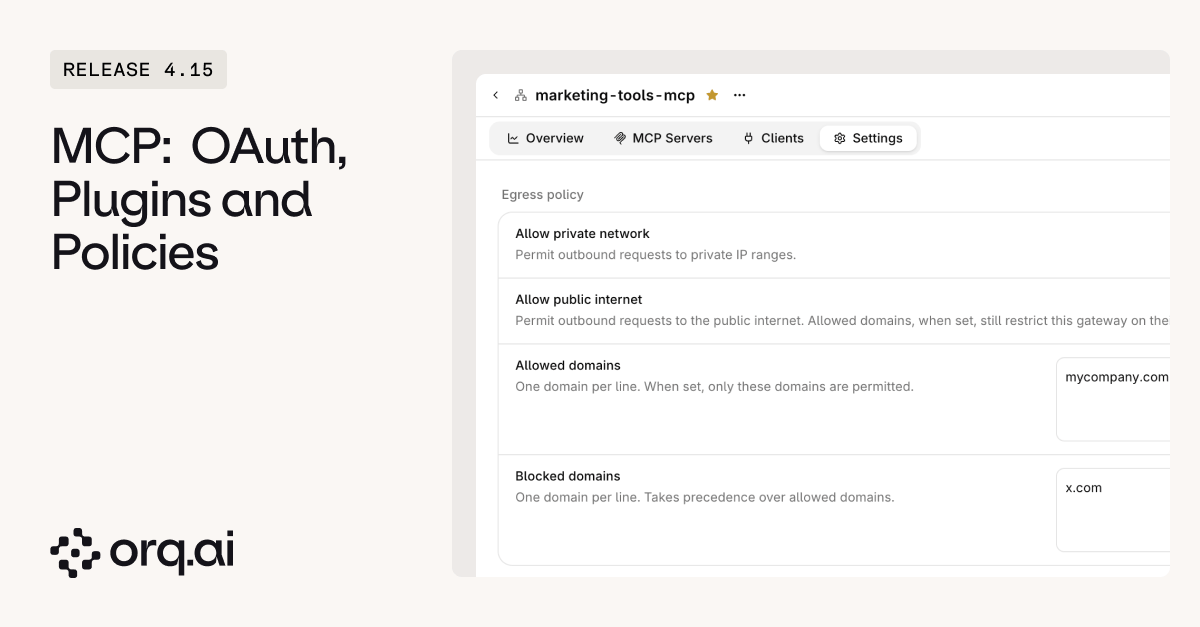 * **[OAuth](https://docs.orq.ai/docs/ai-gateway/mcp-portal/mcp-gateways#oauth) is the default connection**: The client completes a browser sign-in and receives a token scoped to that gateway and to the person who signed in. Nothing long-lived lands in a config file, and existing API key connections keep working.
* **Egress policy and runtime limits**: Allow or block the domains an upstream tool may call and cap execution time, so a misbehaving tool cannot reach an internal address or run unbounded.
* **Plugins on every tool call**: Attach PII redaction or other plugins to a gateway and they run on every call to every server behind it, the same way they run on a Routing rule.
Set up a gateway from the [MCP Gateway](https://docs.orq.ai/docs/ai-gateway/mcp-portal/mcp-gateways) guide.
Write Python **Evaluators** and **Tools** in a real code editor instead of a text box. The editor completes names, flags undefined variables and unused imports while typing, and formats on demand, so a broken **Evaluator** is caught before it ever runs.
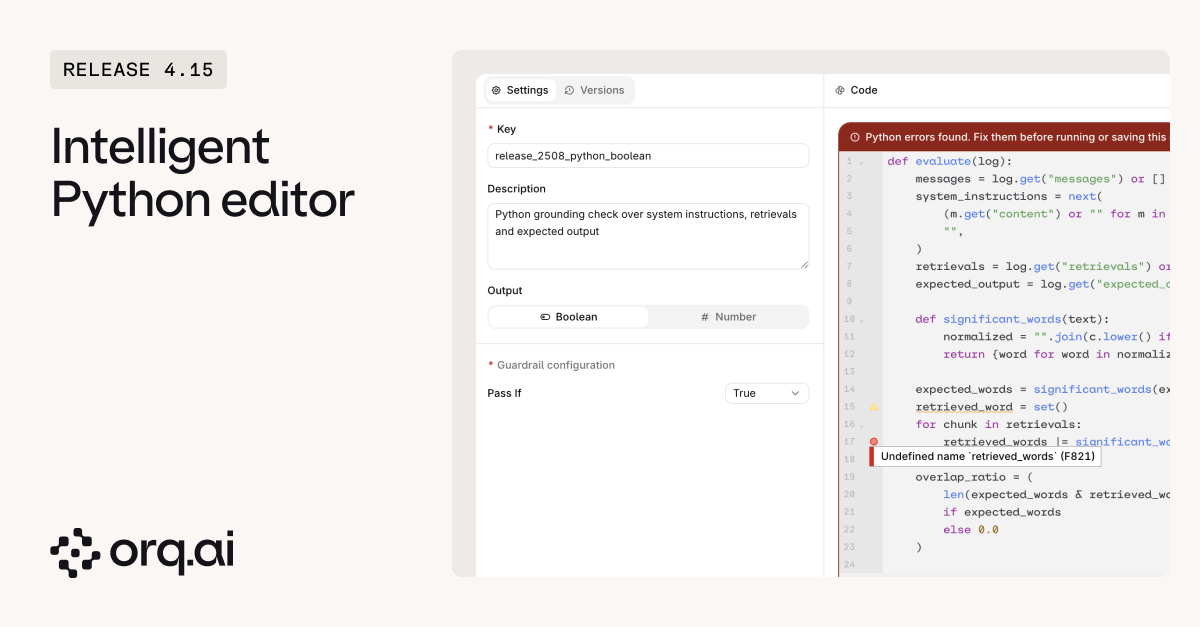 * **Completions that know the runtime**: In an [Evaluator](https://docs.orq.ai/docs/ai-studio/optimize/evaluators), typing `log[` suggests the real keys such as `input`, `output`, and `messages`. In a **Tool**, schema parameters are suggested as variables with their descriptions.
* **Diagnostics with quick fixes**: Undefined names, unused imports and variables, and syntax errors are underlined inline, and runtime-injected globals such as `log` and `params` are recognized so they never show as errors.
* **Format and run**: A Format button and `Shift+Alt+F` apply the Ruff formatter. The **Playground** shows `stdout` separately from the result and returns the real error message instead of a generic failure.
* **Safer publishing**: A **Tool** with invalid Python syntax can no longer be published.
Open any Python **Evaluator** or **Tool** in Studio to use the new editor. See the [Evaluators](https://docs.orq.ai/docs/ai-studio/optimize/evaluators) page for the available variables.
* **[Telemetry API](https://docs.orq.ai/reference/telemetry/query-telemetry) for platform usage (Beta)**: One query at `POST /v3/telemetry/query` returns cost, tokens, latency, and **Evaluator** outcomes over time from traces, metrics, or logs, grouped by **Agent**, **Deployment**, **Identity**, or any dimension, with filters, time buckets, and totals. Build custom dashboards on it. It replaces the [Reporting API](https://docs.orq.ai/docs/ai-studio/observability/reporting-api).
* **[Google GenAI-compatible wire](https://docs.orq.ai/docs/ai-studio/integrations/code-assistants/gemini-cli)**: Gemini CLI and the Google Gen AI SDKs work against the **AI Gateway** under `/v3/google` with no client changes, with Routing rules, Guardrails, budgets, and **Traces** applied as on every other wire.
* **[PII detection and PII redaction](https://docs.orq.ai/docs/ai-gateway/features/plugins/pii-redaction) by region and entity**: Coverage now includes country-specific identifiers for the Netherlands, the United Kingdom, Belgium, Germany, France, and the United States, such as BSN, NHS and NINO numbers, alongside the base entity set. Detection runs as a System guardrail in [Guardrail rules](https://docs.orq.ai/docs/ai-gateway/configuration/guardrail-rules#system-guardrails) to block a request or response outright. Redaction is configured per workspace or per [Routing rule](https://docs.orq.ai/docs/ai-gateway/configuration/routing-rules) and only masks the values sent to the model.
* **[Workspace security](https://docs.orq.ai/docs/ai-studio/organization/workspace-security) tab**: Organization settings gain a Security tab where admins verify workspace domains and restrict backend API requests to approved IPv4 or IPv6 ranges. Enterprise plan.
* **Reasoning tokens in [Traces](https://docs.orq.ai/docs/ai-studio/observability/traces)**: The span properties panel breaks the token total into input, output, and reasoning tokens, so the cost of a reasoning model is visible where cost is inspected.
* **[Alerts](https://docs.orq.ai/docs/ai-studio/observability/alerts) on Deployment Guardrails**: An alert on a **Guardrail** result, an **Evaluator** attached to a **Deployment**, now covers **Deployments** as well as **Agents**, and the alert chart shows the same activity the alert engine evaluates.
* **Human feedback on Deployment runs**: Submit a human review on a **Deployment** run from the run view, and the annotation shows in the Feedback tab.
* **MCP Servers in [Agents](https://docs.orq.ai/docs/ai-studio/ai-engineering/build-agents)**: **MCP Servers** are a separate section in the **Agent** builder rather than a tool type, so attaching a server is a selection instead of a tool definition.
* **[Server tools](https://docs.orq.ai/docs/ai-gateway/features/server-tools) on the AI Gateway**: Add `orq:web_search`, `orq:web_fetch`, `orq:search_models`, `orq:image_generation`, `orq:apply_patch`, `orq:fusion`, `orq:shell`, `orq:subagent`, or `orq:advisor` to the `tools` array and the **AI Gateway** executes the call, on both the Responses and Chat Completions endpoints. Usage is reported under `usage.server_tool_use`.
The [Orq CLI](https://docs.orq.ai/reference/cli) drives the platform from a terminal, CI, or a script, and wires the coding agents on a machine through the **AI Gateway**.
* **Install and set up in one step**: `curl -fsSL https://cli.orq.ai/install.sh | sh`, then `orq setup` signs in and wires every agent it detects.
* **Eight coding agents**: Claude Code, Codex, OpenCode, Kimi Code, Kilo, Pi, GitHub Copilot CLI, and Gemini CLI, wired with `orq connect` per capability (`gateway`, `tracing`, `skills`, `mcp`) or run through `orq launch`.
* **Routed sessions**: `orq launch ` runs an agent through the gateway without writing any config, and `-p` makes it headless for CI.
* **Read a Trace as a conversation**: `orq traces thread` renders a run as readable text in XML, Markdown, JSON, YAML, or TOON.
* **Built for scripts**: Commands return `json`, `yaml`, `toon`, or a table, and `--profile` and `orq switch` select the identity, workspace, and project.
Install and authenticate from the [Orq CLI](https://docs.orq.ai/reference/cli) reference.
* **[Request metadata](https://docs.orq.ai/docs/ai-gateway/request-metadata) via headers**: Coding agents that cannot change the request body can send `X-ORQ-METADATA-` and `X-ORQ-THREAD-ID` headers, so **Traces** can be sliced by repo, branch, or ticket.
* **Cached token pricing**: Custom models and AWS Bedrock models now price cached tokens, so cost reporting reflects cache hits instead of counting them as free.
* **Finer-grained API key permissions**: Permissions can be granted per area, including **Traces**, Logs, **Experiments**, Webhooks, **Annotation Queues**, and SCIM. A key can be created for **Traces** only, for example to let an ingestion pipeline write spans without reaching anything else in the workspace.
* **Evaluators skip failed Agent runs**: An **Evaluator** no longer scores an **Agent** run that ended in an error, so scores reflect completed runs only.
* **AI Chat model parameters**: Temperature and the other model parameters can be set in AI Chat.
* **Model search by name**: Text search in the **Model Garden** and model pickers matches the model name, not only the identifier.
New additions to the **Model Garden**. Browse details on the [Supported Models](https://docs.orq.ai/docs/ai-gateway/supported-models) page.
| Provider | Models |
| ------------- | ----------------------------------------------------------------------------- |
| **Anthropic** | `claude-fable-5-1`, on Anthropic, AWS Bedrock, and Google Vertex AI |
| **OpenAI** | `gpt-6-astra` |
| **Google** | `gemini-3.8-flash`, on both Google Vertex AI and Google AI |
| **Alibaba** | `qwen-qwen3.8-27b` on Cerebras and Groq, `qwen-qwen3.8-flash-next` on TensorX |
| **Cohere** | `parse-v5.0` |
| **Meta** | `muse-voice-transcribe-1.0` |
Existing models reach new providers: `glm-5.3-flash` is now served by **Z.ai**, **Nebius**, and **TensorX**, `glm-5.3` by **Inceptron**, `deepseek-v4-flash` by **Inceptron** and **Nebius**, and `deepseek-v4-pro` by **Nebius**.
* **Router and providers**: GPT-5 models no longer fail on the default temperature, function tools with reasoning work on Chat Completions, images in tool results reach Anthropic models, moderation models are accepted by the moderations endpoint, and an enabled image model invokes instead of returning "model not found".
* **Deployment invoke**: Retries fire on `500`, `503`, and timeouts again rather than only on `429`.
* **Deployment cache**: Cache TTL is no longer capped at 3 days, cache invalidation works, and cache status is shown consistently in logs and webhooks.
* **AWS Bedrock private models**: A private Bedrock model can be used in a **Deployment**.
* **OTLP ingestion**: A client-set span type is preserved so **Evaluator** spans attach as evaluations, oversized attributes are trimmed instead of silently dropping the span, and tool and LLM spans from Strands, Bedrock AgentCore, and LiveKit carry their prompts, replies, and tool arguments.
* **Traces**: OTLP traces from Azure AI Agents and the OpenAI SDK appear in the **Traces** list, tool calls are labeled as tool calls, openai-agents tool spans carry a call id, and streamed **Agent** traces include span details and costs.
* **Studio performance**: The **Agents** list stays responsive with hundreds of agents.
Two surfaces are retired in this release.
* **Legacy sidebar**: Every workspace now uses the new project view. Favorites, project scoping, and the settings menu are unchanged; only the old navigation layout is gone.
* **Control Tower as a separate app**: The app switcher entry is removed. Its Overview and Assets views will be moving into **AI Studio** as an AI Governance section in the future.